Green ABAP for the SAP World
Every digital system requires energy to operate. While hardware is becoming increasingly efficient, inefficient software still forces servers to perform at unnecessarily high levels. Large companies typically manage their business processes using complex SAP systems. The ABAP programming language is at the heart of these applications. In the past, developers often wrote ABAP code with a focus solely on functionality. Today, however, it’s worth paying attention to energy consumption as well. That’s because poor code artificially drives up electricity consumption.
Green ABAP and Clean Code
This is where the „Green ABAP“ approach comes in. This method directly links sustainability goals to software development. „Clean code“ plays a huge role in this. This term describes code that is easy to read and maintain. Clean code reduces errors and simplifies future programming optimizations. Code that is easy to read prevents technical debt, conserves hardware resources in the long term, and contributes to achieving climate goals.
How the Test Was Conducted: The Methodology
We examined the resource consumption of ABAP code in an empirical analysis. We conducted the tests in a standardized SAP S/4HANA environment on a training system. The SAP Workload Monitor (ST03N) accurately recorded the performance metrics.
Throughout the process, we consistently compared old, inefficient programs with optimized versions. The comparison is based on four key metrics: CPU time, database response time, total response time, and the amount of data requested.
Each test was run exactly ten times to prevent random fluctuations in the measured values. Direct power consumption cannot be easily measured in joules in an SAP system. However, the CPU and database times determined are generally considered reliable indicators of energy consumption. The less processing time a program requires, the less power the server consumes. We examined nine typical programming scenarios, and we present the findings and corresponding code examples below.
Case 1: Avoid Database Queries in Loops
We identified repeated database queries as a major performance issue. The inefficient version reads records from the database one row at a time.
Inefficient code:
REPORT zthesis_ineff_select_loop.

DATA: lt_flights TYPE TABLE OF sflight,
 ls_flight  TYPE sflight,
 lv_carrname TYPE scarr-carrname.

" Load all flight records
SELECT * FROM sflight INTO TABLE lt_flights.

" Inefficient: SELECT inside the loop
LOOP AT lt_flights INTO ls_flight.

  SELECT SINGLE carrname INTO lv_carrname
    FROM scarr
    WHERE carrid = ls_flight-carrid.

  WRITE: / ls_flight-carrid, ls_flight-connid, lv_carrname.

ENDLOOP.
To optimize performance, all data is loaded into memory in advance. The program then uses fast internal tables for data matching.
Optimized code:
REPORT zthesis_eff_select_loop.

DATA: lt_flights TYPE TABLE OF sflight,
 lt_scarr   TYPE TABLE OF scarr,
 ls_flight  TYPE sflight,
 ls_scarr   TYPE scarr.

" Load both tables once
SELECT * FROM sflight INTO TABLE lt_flights.
SELECT * FROM scarr INTO TABLE lt_scarr.

" Efficient: in-memory lookup
LOOP AT lt_flights INTO ls_flight.

  READ TABLE lt_scarr INTO ls_scarr WITH KEY carrid = ls_flight-carrid.

  IF sy-subrc = 0.
    WRITE: / ls_flight-carrid, ls_flight-connid, ls_scarr-carrname.
  ENDIF.

ENDLOOP.
As a result of this optimization, the database time was reduced by nearly 99 percent.
Case 2: Inefficient Removal of Duplicates
We tested the ABAP command for deleting duplicates. Without first sorting the data, the system removes only immediately adjacent duplicates.
Inefficient code:
REPORT zthesis_ineff_delete_dupl.

DATA: lt_data TYPE TABLE OF sbook,
 ls_data TYPE sbook.

SELECT * FROM sbook INTO TABLE lt_data
  WHERE customid = '00001234'.

" No sorting before deleting duplicates
DELETE ADJACENT DUPLICATES FROM lt_data
  COMPARING carrid connid.

LOOP AT lt_data INTO ls_data.
  WRITE: / ls_data-carrid, ls_data-connid.
ENDLOOP.
In the optimized version, we added a simple sort command before the deletion.
Optimized code:
REPORT zthesis_opt_delete_dupl.

DATA: lt_data TYPE TABLE OF sbook,
 ls_data TYPE sbook.

SELECT * FROM sbook INTO TABLE lt_data
  WHERE customid = '00001234'.

" Efficient: Sorting before deleting duplicates
SORT lt_data BY carrid connid.

DELETE ADJACENT DUPLICATES FROM lt_data
  COMPARING carrid connid.

LOOP AT lt_data INTO ls_data.
  WRITE: / ls_data-carrid, ls_data-connid.
ENDLOOP.
This small adjustment improved the system's response time by nearly 47 percent. The system now compares the entries much more efficiently.
Case 3: Radically Reduce Data Volumes at the Source
We examined the behavior of unfiltered database queries. The inefficient version thoughtlessly loads the entire data table into memory.
Inefficient code:
REPORT zthesis_ineff_select_where.

SELECT * FROM sflight INTO TABLE @DATA(lt_flights).

LOOP AT lt_flights INTO DATA(ls_flight).
  " Process all flights, even when not needed
  WRITE: / ls_flight-carrid, ls_flight-connid.
ENDLOOP.
We moved the filtering process in the optimization directly to the database level by using a specific “WHERE” clause.
Optimized code:
REPORT zthesis_opt_select_where.

SELECT * FROM sflight
  WHERE carrid = 'LH'
  INTO TABLE @DATA(lt_flights_filtered).

LOOP AT lt_flights_filtered INTO DATA(ls_flight).
  " process only relevant flights
  WRITE: / ls_flight-carrid, ls_flight-connid.
ENDLOOP.
As a result, the amount of data retrieved immediately dropped by more than 73 percent.
Case 4: Comparing Tables Effectively
Nested loops often result in exponential computation times when dealing with large amounts of data. We compared this approach with efficient lookup tables.
Inefficient code:
REPORT zthesis_ineff_nested_loop.

DATA: lt_conn    TYPE TABLE OF spfli,
 lt_flights TYPE TABLE OF sflight.

SELECT * FROM spfli INTO TABLE lt_conn.
SELECT * FROM sflight INTO TABLE lt_flights.

LOOP AT lt_conn INTO DATA(ls_conn).

  LOOP AT lt_flights INTO DATA(ls_flight).

    IF ls_conn-carrid = ls_flight-carrid AND
 ls_conn-connid = ls_flight-connid.

 WRITE: / ls_conn-carrid, ls_conn-connid, ls_flight-fldate.

    ENDIF.

  ENDLOOP.

ENDLOOP.
We converted the second table into a “hashed table” for optimization, so that the program can find matching entries without having to perform extensive searches.
Optimized code:
REPORT zthesis_opt_hashed_lookup.

TYPES: BEGIN OF ty_flight_map,
 carrid TYPE sflight-carrid,
 connid TYPE sflight-connid,
 fldate TYPE sflight-fldate,
 END OF ty_flight_map.

DATA: lt_conn TYPE TABLE OF spfli,
 lt_flight_map TYPE HASHED TABLE OF ty_flight_map
 WITH UNIQUE KEY carrid connid.

SELECT * FROM spfli INTO TABLE lt_conn.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights_small).

LOOP AT lt_flights_small INTO DATA(ls_flight).
  INSERT ls_flight INTO TABLE lt_flight_map.
ENDLOOP.

LOOP AT lt_conn INTO DATA(ls_conn).

  READ TABLE lt_flight_map INTO DATA(ls_match)
    WITH KEY carrid = ls_conn-carrid
             connid = ls_conn-connid.

  IF sy-subrc = 0.
    WRITE: / ls_conn-carrid, ls_conn-connid, ls_match-fldate.
  ENDIF.

ENDLOOP.
This reduced CPU time by more than 71 percent.
Case 5: Modularization of Logic
We examined the effects of well-structured code in detail. Logic executed directly within the program runs linearly.
Inefficient Code (Inline):
REPORT zthesis_no_function.

DATA: lv_sum TYPE i VALUE 0,
 lv_i   TYPE i.

" Calculate the sum of the first 10,000 numbers
DO 10000 TIMES.
  lv_sum = lv_sum + sy-index.
ENDDO.

WRITE: / 'Sum of the first 10,000 numbers:', lv_sum.
We then moved this calculation logic into a separate function module. This minimizes the structural overhead in the system.
Optimized code:
REPORT zthesis_with_function.

DATA: lv_result TYPE i.

CALL FUNCTION 'ZTHESIS_CALC_SUM'
  EXPORTING
    p_limit = 10000
  IMPORTING
    p_sum   = lv_result.

WRITE: / 'Sum of the first 10,000 numbers (Function Module):', lv_result.
The corresponding function module:
FUNCTION zthesis_calc_sum.

  DATA lv_index TYPE i.

  p_sum = 0.

  DO p_limit TIMES.
    lv_index = sy-index.
    p_sum = p_sum + lv_index.
  ENDDO.

ENDFUNCTION.
The modular version delivered virtually identical performance figures. The main advantage here is that it is easier to maintain for future modifications.
Case 6: Procedural vs. Object-Oriented
We compared a simple counting loop with an object-oriented, recursive approach to measure the resource overhead associated with object-oriented programming.
Iterative code:
REPORT zthesis_factorial_iterative.

START-OF-SELECTION.

DATA: lv_number TYPE i VALUE 10,
 lv_result TYPE i VALUE 1.

DO lv_number TIMES.
  lv_result = lv_result * sy-index.
ENDDO.

WRITE: / 'Iterative factorial (loop) of', lv_number, ':', lv_result.
Object-oriented code:
REPORT zthesis_factorial_oop.

CLASS lcl_factorial DEFINITION.

  PUBLIC SECTION.

 METHODS: calculate
 IMPORTING iv_number TYPE i
 RETURNING VALUE(rv_result) TYPE i.

ENDCLASS.

CLASS lcl_factorial IMPLEMENTATION.

  METHOD calculate.

    IF iv_number calculate( 10 ).

WRITE: / 'Recursive factorial (OOP) of 10:', lv_result.
The object-oriented version consumed about 22 percent more CPU time and is not energy-efficient for such simple operations. However, in large-scale architectures, the advantage of scalability outweighs this in the long run.
Case 7: Avoiding “SELECT “
Many developers use the “SELECT *” database command for convenience. When they do, the system blindly loads all the columns in a table.
Inefficient code:
REPORT zthesis_ineff_select_star.

SELECT * FROM sflight
  INTO TABLE @DATA(lt_flights).

LOOP AT lt_flights INTO DATA(ls_flight).
  WRITE: / ls_flight-carrid, ls_flight-connid, ls_flight-fldate.
ENDLOOP.
We modified the code so that we explicitly queried only the exact three columns we needed.
Optimized code:
REPORT zthesis_opt_select_fields.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights_reduced).

LOOP AT lt_flights_reduced INTO DATA(ls_flight).
  WRITE: / ls_flight-carrid, ls_flight-connid, ls_flight-fldate.
ENDLOOP.
This minimal reduction saved over 73 percent of the data volume retrieved.
Case 8: Clear Control Flow
Clean code requires a clear and predictable flow. We analyzed a loop with many scattered termination conditions.
Inefficient code:
REPORT zthesis_ineff_control_flow.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights).

DATA(lv_found) = abap_false.

LOOP AT lt_flights INTO DATA(ls_flight).

  IF ls_flight-carrid IS INITIAL.
    CONTINUE.
  ENDIF.

  IF ls_flight-connid IS INITIAL.
    CONTINUE.
  ENDIF.

  IF ls_flight-fldate IS INITIAL.
    CONTINUE.
  ENDIF.

  IF ls_flight-carrid = 'XX'.
    CONTINUE.
  ELSEIF ls_flight-carrid = 'YY'.
    CONTINUE.
  ENDIF.

  IF ls_flight-connid = '9999'.
    lv_found = abap_true.
    EXIT.
  ENDIF.

  WRITE: / ls_flight-carrid, ls_flight-connid, ls_flight-fldate.

ENDLOOP.

IF lv_found = abap_true.
  WRITE: / 'Special connection found.'.
ENDIF.
To optimize the code, we combined the many jumps into a single, clean control statement.
Optimized code:
REPORT zthesis_opt_control_flow.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights).

DATA(lv_found) = abap_false.

LOOP AT lt_flights INTO DATA(ls_flight).

  IF ls_flight-carrid IS INITIAL
 OR ls_flight-connid IS INITIAL
 OR ls_flight-fldate IS INITIAL
 OR ls_flight-carrid = 'XX'
     OR ls_flight-carrid = 'YY'.

 CONTINUE.

  ENDIF.

  IF ls_flight-connid = '9999'.
    lv_found = abap_true.
    EXIT.
  ENDIF.

  WRITE: / ls_flight-carrid, ls_flight-connid, ls_flight-fldate.

ENDLOOP.

IF lv_found = abap_true.
  WRITE: / 'Special connection found.'.
ENDIF.
This change had virtually no effect on execution time. However, the code is now much more readable and easier to understand.
Case 9: Reducing Unnecessary Memory Usage
Some programs copy large data tables multiple times into memory. They also create huge text buffers.
Inefficient code:
REPORT zthesis_ineff_memory.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights).

DATA(lt_copy1) = lt_flights.
DATA(lt_copy2) = lt_copy1.

DATA lv_buffer TYPE string.

LOOP AT lt_copy2 INTO DATA(ls_flight).

  CONCATENATE lv_buffer
 ls_flight-carrid
 ls_flight-connid
 ls_flight-fldate
    INTO lv_buffer
    SEPARATED BY space.

ENDLOOP.

WRITE: / lines( lt_copy2 ).
We processed the original data directly in the optimized version and avoided creating unnecessary intermediate copies.
Optimized code:
REPORT zthesis_opt_memory.

SELECT carrid, connid, fldate
  FROM sflight
  INTO TABLE @DATA(lt_flights).

DATA lv_count TYPE i.

lv_count = 0.

LOOP AT lt_flights INTO DATA(ls_flight).
  lv_count = lv_count + 1.
ENDLOOP.

WRITE: / lv_count.
CPU time dropped by more than 33 percent as a result of this direct access.
Overview of Savings
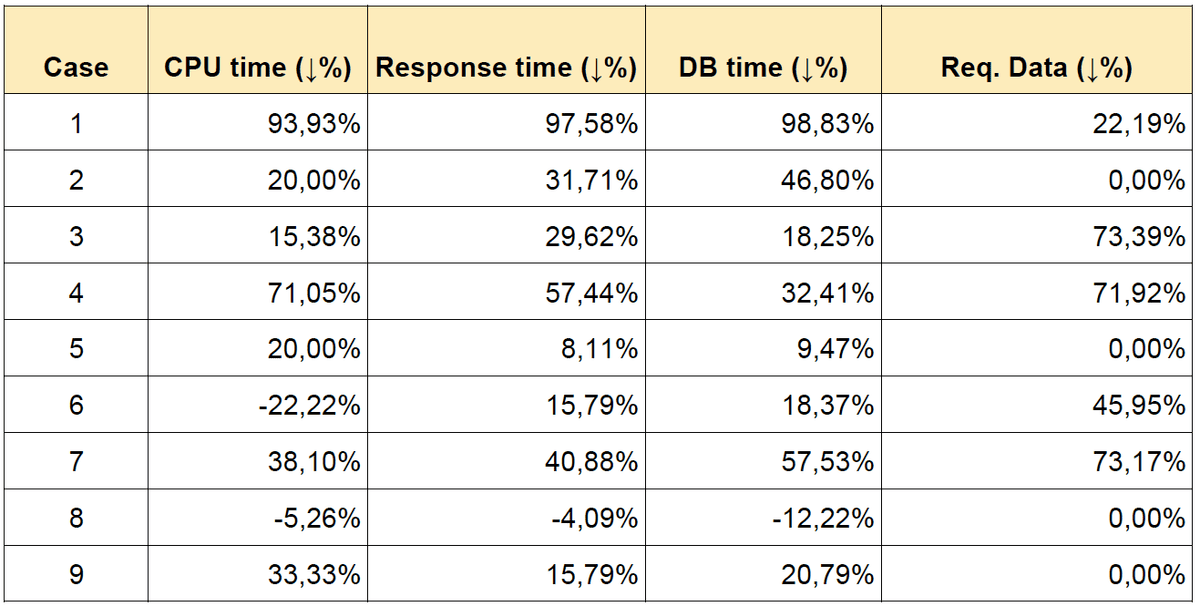
Some of the results of the optimization experiments are quite clear. Eliminating database queries within loops reduced database time by nearly 99 percent. CPU time fell by almost 94 percent in this particular test.
Filtering using a „WHERE“ condition reduced the amount of data retrieved from the server by over 73 percent. Avoiding the convenient „SELECT *“ statement also saved more than 73 percent of the requested data. Clever hashed tables reduced the CPU load when comparing tables by a remarkable 71 percent.
Across all nine cases examined, CPU time was reduced by a remarkable 20 to 90 percent in most instances. Database times also decreased dramatically, by 30 to nearly 99 percent. Table 1 provides a complete overview.
Conclusion
Green ABAP has yet to receive much attention, but it is a solid strategy for a far superior software architecture. Optimized code drastically reduces a system’s power consumption. It reduces the load on hardware, lowers a company’s energy costs, and is good for the environment. Development teams need to break a few old habits. Database queries must be strictly bundled, and the amount of data transferred must be kept to a minimum. Tools such as the SAP Code Inspector help with systematic implementation.
Ever since the introduction of HANA database technology, SAP has been promoting "code pushdown"—that is, the systematic offloading of computational tasks to the database layer. Sustainable programming combines technical excellence with important climate protection. Every optimized block of code thus makes a tangible contribution to greener information technology.
 Deutsch
 English
 Español
 Français